Voices from Online Labour: Inequalities in digital earning activities across countries (VOLI) is a research project that I have been leading since 2024, with funding from ANR. VOLI gives a voice to the often overlooked, yet essential data workers who power the global production of artificial intelligence (AI). Mostly recruited through international digital platforms for short-term “gigs,” these workers transcribe audio, label images, or refine prompts. As in prior waves of globalization, this outsourced and delocalized form of labor triggers new vulnerabilities, especially in already marginalized Global South countries. At the same time, long-standing inequalities tied to gender, social class, or ethnic origin persist in these environments. VOLI aims to unpack the complex interplay between these factors at the intersection of online platform work, global AI supply chains, and social inequality. Focus is on the ramifications of this phenomenon in Latin America, home to a vast pool of data workers.
This project earned PRIME recognition (CNRS’s label that characterizes the teams’ commitment to interdisciplinarity) for its approach that combines sociology and large-scale corpus linguistics, supported by speech technology and AI itself. We collect oral narrations from data workers, and we analyse them sociologically and linguistically. We expect language use to reflect their professional roles in AI and to reveal nuances that traditional socioeconomic variables may miss. We thereby aim to draw a detailed typology of data workers, while simultaneously advancing linguistic research on spoken language variation in Spanish and Portuguese. For example, we explore the effects of linguistic contact beyond migration and reexamine the link between linguistic and social inequalities in highly educated but economically disadvantaged workers.
This project addresses three key sets of challenges. From a social science perspective, VOLI tackles open questions in two areas: digital inequality and online labor. While inequality research focuses on the divide between digitally connected and disconnected groups, it often ignores the risks of platform work. Labor studies highlight precarity and the erosion of traditional employment but overlook disparities among workers, risking their reinforcement. VOLI compares workers within platforms to reveal how class, gender, education, or location shape their conditions.
On the linguistic front, VOLI advances the study of language variation tied to sociodemographic traits. It enables analysis of hard-to-define populations (geographically dispersed or without a shared workplace) by leveraging rich data: interviews converted into speech databases, supplemented by questionnaires that provide metadata.
Finally, the project helps improve automated speech recognition systems for social research. By providing diverse data and precise descriptions of speech variation, it allows developing cleaner transcriptions—free of hesitations or disfluencies, with proper punctuation—making them suitable for broad use.
There are two main ways in which a discipline like sociology engages with artificial intelligence (AI) and is affected by it. In a previous post, I discussed how the sociology of AI understands technology as embedded in socio-economic systems and takes it as an object for research. Here, focus is on sociology with AI, indicating that the discipline is integrating AI into its methodological toolbox.
AI technologies were designed for other-than-research purposes, but they may be repurposed. The editors of a special issue of Sociologica last year stress that, ten years ago, digital methods presented similar challenges: for example, using tweets to make claims about the social world required us to understand how people used Twitter in the first place. We also needed to understand which people used Twitter at all, and what spaces of action the architecture and Terms of Use of this platform allowed. Likewise, using AI technologies can serve sociologists insofar as efforts are made to understand the technological (and socio-economic) conditions that produced them. Because AI systems are typically blackboxed, this requires, to begin with, developing exploration techniques to navigate them. For example, the plot below is from a recent paper that asked five different LLMs to generate religious sermons and compared the results (readability scores) by religious traditions and race. It finds that Jewish and Muslim synthetic sermons were constructed with significantly more difficult reading levels than were those for evangelical Protestants, and that Asian religious leaders were assigned more difficult texts than other groups. It is a way to uncover how models treat religious and racial groups differently, although it remains difficult to detect precisely which factors affect this result.
Robust regression coefficients predicting readability scores by religion, race, and model. Source: Tom J.C., Ferguson T.W. & Martinez B.C. 2025. Religion and racial bias in Artificial Intelligence Large Language Models. Socius: Sociological Research for a Dynamic World, 11. https://doi.org/10.1177/23780231251377210
That said, how can AI help us methodologically? To answer this question, it is useful to look at qualitative and quantitative approaches separately. Qualitative research, traditionally viewed and practiced as an intensely human-centred method, may seem at first sight incompatible with it. However, use of computer-assisted qualitative data analysis (with tools such as Nvivo) is now common among qualitative researchers, though it faced some degree of scepticism at the beginning. Attempts to leverage AI move forward this agenda, and the most common application so far is automated transcription of interviews through speech recognition technologies. AI-powered tools make this otherwise tedious task more efficient and scalable. A recent special issue of the International Journal of Qualitative Methods maps a variety of other usages, less common and more experimental: for example, considering that even the best models for audio transcription are not as accurate as humans, LLMs appear as tools to facilitate and speed up transcription cleaning. There are also some attempts at using LLMs as instruments for coding and thematic analysis: for example, some authors have examined inter-coder reliability between ‘human only’ and ‘human-AI’ approaches. Others have used AI image generation like vignettes – as a tool for supporting interview participants in articulating their experiences. Overall, the use of AI remains experimental and marginal in the qualitative research community. Those who have undertaken these experiments find the results encouraging, but not perfect.
In quantitative research, some AI tools are already (relatively) widely used: in particular, natural language processing (NLP) to process textual data like corpora from the press or media. More recent applications leverage generative AI, especially large language models (LLM). Outside practices like literature review and code generation/debugging, which are common to multiple disciplines, three applications are specifically sociological and worth mentioning. First, in experimental research, there are some attempts to examine how the introduction of AI agents in interaction games shapes the behaviour of the humans they play with. As discussed by C. Bail in an insightful PNAS article, the extent to which generative AI is capable of impersonating humans is nevertheless subject to debate, and it will probably evolve over time. Second, L. Rossi and co-authors outline that in agent-based models (ABM), an idea is to use LLMs to create agents that are more capable of capturing a larger spectrum of human behaviours. While this approach may provide more realistic descriptions of agents, it re-ignites a long-standing debate in the field: indeed, many believe that increasing the complexity of agents is undesirable when emergent collective dynamics can emerge from more parsimonious models. It is also unclear how the performance of LLMs within ABMs should be evaluated. Shall we say that they are good if they reproduce known collective dynamics within ABMS? Or, should they be assessed based upon their capacity to predict real-world outcomes? Third, in survey research, the question has arisen whether LLMs can simulate human populations for opinion research. Some studies have tested this possibility, with mixed results. The most recent available evidence, in an article by J. Boelaert and co-authors, is that: 1) current LLMs fail to accurately predict human responses, 2) they do so in ways that are unpredictable, as they do not systematically favor specific social groups, and 3) their answers exhibit a substantially lower variance between subpopulations than what is found in real-world human data. In passing, this is evidence that so-called ‘bias’ does not necessarily operate as expected – LLM errors do not stem primarily from unbalanced training data.
These applications face specific ethical challenges. First, studies that require humans to interact with AI may expose them to offensive or inaccurate information, the so-called ‘AI hallucinations’. Second, there are new concerns about privacy and confidentiality. Most GenAI models are the private property of companies: if we use them to code in-depth interviews about a sensitive topic, the full content of these interviews may be shared with these companies, often not bound by the same standards and regulations in terms of personal data protection. Third, the environmental impact of these models is high, in terms of energy to run the system, water to cool servers in data centres, metal extraction to build devices, and production of e-waste. The literature on AI-as-object also warns that there is a cost in terms of the unprotected human work of annotators.
Another limitation is that is that research with Generative AI is difficult to replicate. These models are probabilistic in nature: even identical prompts may produce different outputs, in ways that are not well understood as of today. Also, models are constantly being fine-tuned by their producers in ways that we as users do not control. Finally, different LLMs have been found to produce substantially different results in some cases. Many of these issues are due to the proprietary nature of most models – so much so that some authors like C. Bail believe that open-source models devoted to, and controlled by, researchers can help address some of these challenges.
Overall, AI has slowly entered the toolbox of the sociologist, and except for some applications that are now commonplace (from automated transcriptions to NLP), its use has not completely revolutionised practices. This pattern is not exclusive to sociology. My own study of the diffusion of AI in science until 2021, as part of the ScientIA project led by F. Gargiulo, showed limited penetration in almost all disciplines, although the last two years have seen a major acceleration. The opportunities that AI offers are promising, although a lot are more hypothetical than real at the moment. We still see calls that invite sociologists and social scientists to embrace AI, but the number of realizations is still small. Almost all applications devote time to consider the epistemological, methodological, and substantive implications. A question that often emerges concerns the nature of bias. The AI-as-object perspective challenges the language of bias, and we see the same here, though from a different perspective. There’s still no shared definition of bias (or any substitute for this term). More generally, patterns are similar in qualitative and quantitative studies. The guest-editors of last year’s special issue of Sociologicasuggest that, like digital methods 10-15 years ago, generative AI is supporting a move beyond the traditional qualitative/quantitative divide.
Concluding, both Sociology-of-AI and Sociology-with-AI exist and are important, but they are not well integrated. This is one of the bottlenecks for the development of the methodological toolbox of sociology, but also for the development of an AI that is useful and positive for people and societies. In part, this may be due to lack of adequate (technical) training for part of the profession, or to the absence of guidelines (for ethics and/or scientific integrity). But perhaps, the real obstacles are less immediately visible. One of them is the difficulty to judge the uptake of AI in our discipline: are we just feeding the hype if we use it? Or are we missing a major opportunity to make sociology more relevant/stronger if we don’t? The other concerns the questions and issues that go beyond the specificities of sociology. How to continue interacting with other disciplines, while upholding the distinctive contribution of sociology?
There are two main ways in which a discipline like sociology engages with artificial intelligence (AI) and is affected by it. The sociology of AI understands technology as embedded in socio-economic systems and takes it as an object for research. Sociology with AI indicates that the discipline is also integrating AI into its methodological toolbox. Based on a talk that I gave at this year’s annual meeting of the European Academy of Sociology, I’ll give in what follows a brief overview of both. As a disclaimer, I have no pretention to be exhaustive. To narrow down the topic, I have chosen to focus on sociology specifically (rather than neighboring fields), and to rely only on already published, peer-reviewed research.
Let’s start with the sociology of AI, which I’ll illustrate with the help of the above artwork. Its aim is to demonstrate that even if there is a sense of magic in looking at the outputs of an AI system, the data on which it is based has a human origin. This work explores this idea through the symbolism of the mirror and reflection: beyond the magic, these outputs are a reflection of society. Sociological perspectives matter because they can help bring these social and human origins to the fore. In 2021, Kelly Joyce and her coauthors called for more engagement of sociologists in outlining a research agenda around these topics. Compared to other disciplines, we have a thicker understanding of the intersectional inequalities and social structures that interact with AI.
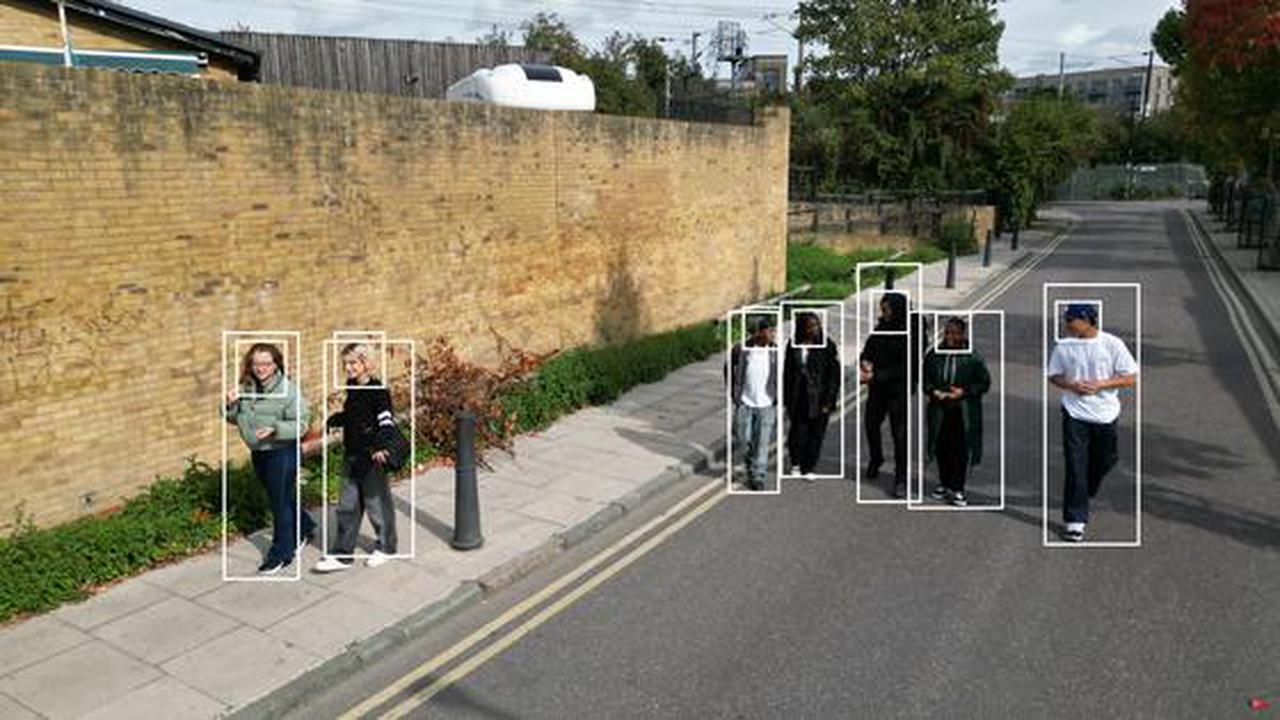
Why does the quasi-absence of sociology matter? I’ll answer this question through a 2022 paper, written by two sociologists but published in a computer science conference. The starting point is that early studies framed AI-related societal problems in terms of bias. For example, the above-mentioned report on predictive policing was entitled “machine bias”. This language points to technical corrections as remedy, but it cannot account for the social processes underway that comprise, among other things, increasing surveillance and privacy intrusion to collect more and more data (see image below). De-biasing may thus be insufficient to prevent injustice or inequality. A sociologically informed approach reveals that key questions are about power: who owns data and systems, whose worldviews are being imposed, whose biases we are trying to mitigate.
In recent years, more substantial contributions have been made within sociology. For example, there was a special issue of Socius last year on “Sociology of Artificial Intelligence”, and another one is forthcoming in Social Science Computer Review, entitled “What is Sociological About AI?”. I’ll mention a non-exhaustive selection of topics and findings. First, sociologists have recognized the hype – or how financial, political, and other interests have boosted the circulation of (often) exaggerated claims. This means shifting the gaze from AI as an intellectual endeavor, to see AI as a market – where bubbles can, well, form. This also means recognizing the political dimensions of AI development, with many states using public funding as a crucial engine for innovation.
Second, AI practitioners engage in a form of social construction of morality to legitimate their approaches to AI. For example, some distance themselves from Big Tech capitalism, some insist on the benefits of some AI applications, most prominently in healthcare. These efforts ultimately shape which technologies gain visibility and attract capital investments. This is also a way through which they produce and sustain the AI bubble itself – a culturally embedded market phenomenon. Third, sociological analysis can move beyond the technological determinism of early AI critics to emphasize the social and institutional contexts within which such algorithmic decision-making systems are deployed. This brings to light forms of negotiation, adaptation, and resistance, which have more subtle effects on inequalities.
In sum, sociologists increasingly contribute to these conversations, although these topics are not prominent in the discipline’s flagship conferences and journals, and important knowledge gaps remain. The guest-editors of the forthcoming Social Science Computer Review special issue on “What is sociological about AI?” claim that “A sociological lens can render AI’s hidden processes legible, just as sociologists have done with complex and taken for granted social forces since the discipline’s inception”. They nevertheless note that “we neither have a robust concept of AI as a social phenomenon nor a holistic sociological discourse around it, despite vibrant and dynamic work in the area.” In passing, most extant studies rely on traditional methods, primarily surveys and fieldwork. This is not an issue in itself, but it highlights a disconnection with the sub-topic I’ll highlight in my next post – Sociology using AI as instrument.
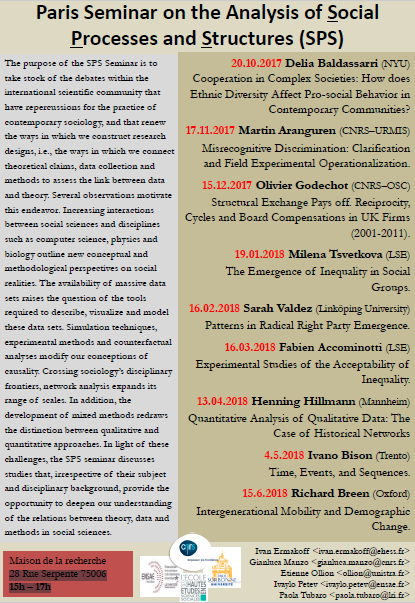
Our inter-disciplinary, inter-institutional SPS seminar (Paris Seminar on the Analysis of Social Processes and Structures) has just started its second edition! Its purpose is to take stock of the debates within the international scientific community that have repercussions on the practice of contemporary sociology, and that renew the ways in which we construct research designs, i.e., the ways in which we connect theoretical claims, data collection and methods to assess the link between data and theory. Several observations motivate this endeavor. Increasing interactions between social sciences and disciplines such as computer science, physics and biology outline new conceptual and methodological perspectives on social realities. The availability of massive data sets raises the question of the tools required to describe, visualize and model these data sets. Simulation techniques, experimental methods and counterfactual analyses modify our conceptions of causality. Crossing sociology’s disciplinary frontiers, network analysis expands its range of scales. In addition, the development of mixed methods redraws the distinction between qualitative and quantitative approaches. In light of these challenges, the SPS seminar discusses studies that, irrespective of their subject and disciplinary background, provide the opportunity to deepen our understanding of the relations between theory, data and methods in social sciences.
I’m excited to report that earlier this month, I ran the second wave of data collection for our Sharing Networks research project at OuiShare Fest 2017!
Publicizing the survey at OuiShare Fest 2017
To understand how people form and reinforce face-to-face network ties at such an event, I fielded a questionnaire with the help of a committed and effective team of co-researchers. It is a “name generator” asking respondents to name those they knew before the OuiShare Fest, and met again there (“old frields”); and those they met during the event for the first time (“new contacts”). Participants then have to choose those among their “old” and “new” contacts, that they would like to contact again in future for joint projects or collaborations.
Interestingly, my good old pen-and-paper questionnaire still gives a lot of insight that digital data from social media cannot provide – just like a highly computer literate community such as this feels the need to meet physically in one place every year for a few days. Like trade fairs that flourish even more in the internet era, the OuiShare Fest gathers more participants at each edition. They meet in person there, which is why they are to be invited to respond in person too.
Each speaker briefly presented a case study that involved visualization, and all were great in conveying exciting albeit complex ideas in a short time span. What follows is a short summary of the main insight (as I saw it).
This new Social Processes and Structures (SPS) Seminar aims to take stock of the debates within the international scientific community that have repercussions for the practice of contemporary sociology, and that renew the ways in which we construct research designs, i.e., the ways in which we connect theoretical claims, data collection and methods to assess the link between data and theory. Several observations motivate this endeavor. Increasing interactions between social sciences and disciplines such as computer science, physics and biology outline new conceptual and methodological perspectives on social realities. The availability of massive data sets raises the question of the tools required to describe, visualize and model these data sets. Simulation techniques, experimental methods and counterfactual analyses modify our conceptions of causality. Crossing sociology’s disciplinary frontiers, network analysis expands its range of scales. In addition, the development of mixed methods redraws the distinction between qualitative and quantitative approaches. In light of these challenges, the SPS seminar discusses studies that, no matter their subject and disciplinary background, provide the opportunity to deepen our understanding of the relations between theory, data and methods in social sciences.
The inaugural session took place on 20 November 2016; the “regular” series starts this Friday, 27 January, and will continue until June, with one meeting per month.
All sessions take place at Maison de la Recherche, 28 rue Serpente, 75006 Paris, room D040, 5pm-7pm. All interested students and scholars are welcome, and there is no need to register in advance.
Revue Française de Sociologie invites article proposals for a special issue on “Big Data, Societies and Social Sciences”, edited by Gilles Bastin (PACTE, Sciences Po Grenoble) and myself.
Focus is on two inextricably interwoven questions: how do big data transform society? How do big data affect social science practices?
Substantive as well as epistemological / methodological contributions are welcome. We are particularly interested in proposals that examine the social effects and/or the scientific implications of big data based on first-hand experience in the field.
The deadline for submission of extended abstracts is 28 February 2017; for full contributions, it is 15 September 2017. Revue Française de Sociologie accepts articles in French or English.
Further details and guidelines for submission are in the call for papers.
Just attended the 20th conference of AISLF, the international association of French-speaking sociologists, in Montréal. Back home yesterday I found a state of fear and madness (again, alas…). But before that, I enjoyed a nice time with fellow researchers from France and (perhaps even more intriguingly, or simply more newly) from the different countries in which French is spoken, ranging from Canada, Belgium and Switzerland to several African countries. It was a good opportunity to get a sense of what research is done around us.
Credit: @ArthurRenault on Twitter (#AISLF2016)
Lots of good presentations. Interestingly, digital sociology appears to be on the up, as many researchers investigated topics that had to do with digital technologies, their usages, and the ensuing economic and social transformations. That there was no dedicated stream is not in itself a problem: if digital technologies permeate all our lives, they should not be studied in a separate subfield but as part of the sociology of work, of gender, of education etc.
The other good thing is the emergence of social networks research in two keynote presentations – by Antonio A. Casilli and Michel Grossetti – which is far from a small achievement, considering that the association does not have a dedicated social networks research group (I would love to see one being created sooner or later… like BSA-SNAG, the group I convene for British Sociological Association).