Voices from Online Labour: Inequalities in digital earning activities across countries (VOLI) is a research project that I have been leading since 2024, with funding from ANR. VOLI gives a voice to the often overlooked, yet essential data workers who power the global production of artificial intelligence (AI). Mostly recruited through international digital platforms for short-term “gigs,” these workers transcribe audio, label images, or refine prompts. As in prior waves of globalization, this outsourced and delocalized form of labor triggers new vulnerabilities, especially in already marginalized Global South countries. At the same time, long-standing inequalities tied to gender, social class, or ethnic origin persist in these environments. VOLI aims to unpack the complex interplay between these factors at the intersection of online platform work, global AI supply chains, and social inequality. Focus is on the ramifications of this phenomenon in Latin America, home to a vast pool of data workers.
This project earned PRIME recognition (CNRS’s label that characterizes the teams’ commitment to interdisciplinarity) for its approach that combines sociology and large-scale corpus linguistics, supported by speech technology and AI itself. We collect oral narrations from data workers, and we analyse them sociologically and linguistically. We expect language use to reflect their professional roles in AI and to reveal nuances that traditional socioeconomic variables may miss. We thereby aim to draw a detailed typology of data workers, while simultaneously advancing linguistic research on spoken language variation in Spanish and Portuguese. For example, we explore the effects of linguistic contact beyond migration and reexamine the link between linguistic and social inequalities in highly educated but economically disadvantaged workers.
This project addresses three key sets of challenges. From a social science perspective, VOLI tackles open questions in two areas: digital inequality and online labor. While inequality research focuses on the divide between digitally connected and disconnected groups, it often ignores the risks of platform work. Labor studies highlight precarity and the erosion of traditional employment but overlook disparities among workers, risking their reinforcement. VOLI compares workers within platforms to reveal how class, gender, education, or location shape their conditions.
On the linguistic front, VOLI advances the study of language variation tied to sociodemographic traits. It enables analysis of hard-to-define populations (geographically dispersed or without a shared workplace) by leveraging rich data: interviews converted into speech databases, supplemented by questionnaires that provide metadata.
Finally, the project helps improve automated speech recognition systems for social research. By providing diverse data and precise descriptions of speech variation, it allows developing cleaner transcriptions—free of hesitations or disfluencies, with proper punctuation—making them suitable for broad use.
There are two main ways in which a discipline like sociology engages with artificial intelligence (AI) and is affected by it. In a previous post, I discussed how the sociology of AI understands technology as embedded in socio-economic systems and takes it as an object for research. Here, focus is on sociology with AI, indicating that the discipline is integrating AI into its methodological toolbox.
AI technologies were designed for other-than-research purposes, but they may be repurposed. The editors of a special issue of Sociologica last year stress that, ten years ago, digital methods presented similar challenges: for example, using tweets to make claims about the social world required us to understand how people used Twitter in the first place. We also needed to understand which people used Twitter at all, and what spaces of action the architecture and Terms of Use of this platform allowed. Likewise, using AI technologies can serve sociologists insofar as efforts are made to understand the technological (and socio-economic) conditions that produced them. Because AI systems are typically blackboxed, this requires, to begin with, developing exploration techniques to navigate them. For example, the plot below is from a recent paper that asked five different LLMs to generate religious sermons and compared the results (readability scores) by religious traditions and race. It finds that Jewish and Muslim synthetic sermons were constructed with significantly more difficult reading levels than were those for evangelical Protestants, and that Asian religious leaders were assigned more difficult texts than other groups. It is a way to uncover how models treat religious and racial groups differently, although it remains difficult to detect precisely which factors affect this result.
Robust regression coefficients predicting readability scores by religion, race, and model. Source: Tom J.C., Ferguson T.W. & Martinez B.C. 2025. Religion and racial bias in Artificial Intelligence Large Language Models. Socius: Sociological Research for a Dynamic World, 11. https://doi.org/10.1177/23780231251377210
That said, how can AI help us methodologically? To answer this question, it is useful to look at qualitative and quantitative approaches separately. Qualitative research, traditionally viewed and practiced as an intensely human-centred method, may seem at first sight incompatible with it. However, use of computer-assisted qualitative data analysis (with tools such as Nvivo) is now common among qualitative researchers, though it faced some degree of scepticism at the beginning. Attempts to leverage AI move forward this agenda, and the most common application so far is automated transcription of interviews through speech recognition technologies. AI-powered tools make this otherwise tedious task more efficient and scalable. A recent special issue of the International Journal of Qualitative Methods maps a variety of other usages, less common and more experimental: for example, considering that even the best models for audio transcription are not as accurate as humans, LLMs appear as tools to facilitate and speed up transcription cleaning. There are also some attempts at using LLMs as instruments for coding and thematic analysis: for example, some authors have examined inter-coder reliability between ‘human only’ and ‘human-AI’ approaches. Others have used AI image generation like vignettes – as a tool for supporting interview participants in articulating their experiences. Overall, the use of AI remains experimental and marginal in the qualitative research community. Those who have undertaken these experiments find the results encouraging, but not perfect.
In quantitative research, some AI tools are already (relatively) widely used: in particular, natural language processing (NLP) to process textual data like corpora from the press or media. More recent applications leverage generative AI, especially large language models (LLM). Outside practices like literature review and code generation/debugging, which are common to multiple disciplines, three applications are specifically sociological and worth mentioning. First, in experimental research, there are some attempts to examine how the introduction of AI agents in interaction games shapes the behaviour of the humans they play with. As discussed by C. Bail in an insightful PNAS article, the extent to which generative AI is capable of impersonating humans is nevertheless subject to debate, and it will probably evolve over time. Second, L. Rossi and co-authors outline that in agent-based models (ABM), an idea is to use LLMs to create agents that are more capable of capturing a larger spectrum of human behaviours. While this approach may provide more realistic descriptions of agents, it re-ignites a long-standing debate in the field: indeed, many believe that increasing the complexity of agents is undesirable when emergent collective dynamics can emerge from more parsimonious models. It is also unclear how the performance of LLMs within ABMs should be evaluated. Shall we say that they are good if they reproduce known collective dynamics within ABMS? Or, should they be assessed based upon their capacity to predict real-world outcomes? Third, in survey research, the question has arisen whether LLMs can simulate human populations for opinion research. Some studies have tested this possibility, with mixed results. The most recent available evidence, in an article by J. Boelaert and co-authors, is that: 1) current LLMs fail to accurately predict human responses, 2) they do so in ways that are unpredictable, as they do not systematically favor specific social groups, and 3) their answers exhibit a substantially lower variance between subpopulations than what is found in real-world human data. In passing, this is evidence that so-called ‘bias’ does not necessarily operate as expected – LLM errors do not stem primarily from unbalanced training data.
These applications face specific ethical challenges. First, studies that require humans to interact with AI may expose them to offensive or inaccurate information, the so-called ‘AI hallucinations’. Second, there are new concerns about privacy and confidentiality. Most GenAI models are the private property of companies: if we use them to code in-depth interviews about a sensitive topic, the full content of these interviews may be shared with these companies, often not bound by the same standards and regulations in terms of personal data protection. Third, the environmental impact of these models is high, in terms of energy to run the system, water to cool servers in data centres, metal extraction to build devices, and production of e-waste. The literature on AI-as-object also warns that there is a cost in terms of the unprotected human work of annotators.
Another limitation is that is that research with Generative AI is difficult to replicate. These models are probabilistic in nature: even identical prompts may produce different outputs, in ways that are not well understood as of today. Also, models are constantly being fine-tuned by their producers in ways that we as users do not control. Finally, different LLMs have been found to produce substantially different results in some cases. Many of these issues are due to the proprietary nature of most models – so much so that some authors like C. Bail believe that open-source models devoted to, and controlled by, researchers can help address some of these challenges.
Overall, AI has slowly entered the toolbox of the sociologist, and except for some applications that are now commonplace (from automated transcriptions to NLP), its use has not completely revolutionised practices. This pattern is not exclusive to sociology. My own study of the diffusion of AI in science until 2021, as part of the ScientIA project led by F. Gargiulo, showed limited penetration in almost all disciplines, although the last two years have seen a major acceleration. The opportunities that AI offers are promising, although a lot are more hypothetical than real at the moment. We still see calls that invite sociologists and social scientists to embrace AI, but the number of realizations is still small. Almost all applications devote time to consider the epistemological, methodological, and substantive implications. A question that often emerges concerns the nature of bias. The AI-as-object perspective challenges the language of bias, and we see the same here, though from a different perspective. There’s still no shared definition of bias (or any substitute for this term). More generally, patterns are similar in qualitative and quantitative studies. The guest-editors of last year’s special issue of Sociologicasuggest that, like digital methods 10-15 years ago, generative AI is supporting a move beyond the traditional qualitative/quantitative divide.
Concluding, both Sociology-of-AI and Sociology-with-AI exist and are important, but they are not well integrated. This is one of the bottlenecks for the development of the methodological toolbox of sociology, but also for the development of an AI that is useful and positive for people and societies. In part, this may be due to lack of adequate (technical) training for part of the profession, or to the absence of guidelines (for ethics and/or scientific integrity). But perhaps, the real obstacles are less immediately visible. One of them is the difficulty to judge the uptake of AI in our discipline: are we just feeding the hype if we use it? Or are we missing a major opportunity to make sociology more relevant/stronger if we don’t? The other concerns the questions and issues that go beyond the specificities of sociology. How to continue interacting with other disciplines, while upholding the distinctive contribution of sociology?
My great regret is that I always have very little time to write posts, and the emptiness of this blog does not reflect the numerous, great and stimulating scientific events and opportunities that I have enjoyed throughout 2024. As a last-minute remedy (with a promise to do better next year…hopefully), I try to summarize the landmarks here, month by month.
In January, I launched the Voices from Online Labour (VOLI) project, which I coordinate with a grant of about €570,000 from the French National Agency for Research. This four-year initiative brings together expertise from sociology, linguistics, and AI technology across multiple institutions, including four French research centres, a speech technology company, and three international partners.
In February with the Diplab team, I spent two exciting days at the European Parliament in Brussels, engaging in profound discussions with and about platform workers as part of the 4th edition of the Transnational Forum on Alternatives to Uberization. I chaired a panel with data workers and content moderators from Europe and beyond, aiming to raise awareness about the difficult working conditions of those who fuel artificial intelligence and ensure safe participation to social media.
In March, three publications saw the light. One is a solo-authored chapter, in French, on ‘Algorithmes, inégalités, et les humains dans la boucle‘ (Algorithms, inequalities, and the humans in the loop) in a collective book entitled ‘Ce qui échappe à l’intelligence artificielle‘ (What AI cannot do). The other two are journal articles that may seem a little less close to my ‘usual’ topics, but they are important because they constitute experiments in research-informed teaching. One is a study of the 15-minute city concept applied to Paris, realized in collaboration with a colleague, S. Berkemer of Ecole Polytechnique, and a team of brilliant ENSAE students. The other is an analysis of the penetration of AI into a specific field of research, neuroscience, showing that for all its alleged potential, it created a confined subfield but did not entirely disrupt the discipline. The study, part of a larger project on AI in science, was part of the PhD research of S. Fontaine (who has now got his degree!), also co-authored with his co-supervisors F. Gargiulo and M. Dubois.
In April, I co-published the final report from the study realized for the European Parliament, ‘Who Trains the Data for European Artificial Intelligence?‘. Despite massive offshoring of data tasks to lower-income countries in the Global South, we find that there are still data workers in Europe. They often live in countries where standard labour markets are weaker, like Portugal, Italy and Spain; in more dynamic countries like Germany and France, they are often immigrants. They do data work because they lack sufficiently good alternative opportunities, although most of them are young and highly educated.
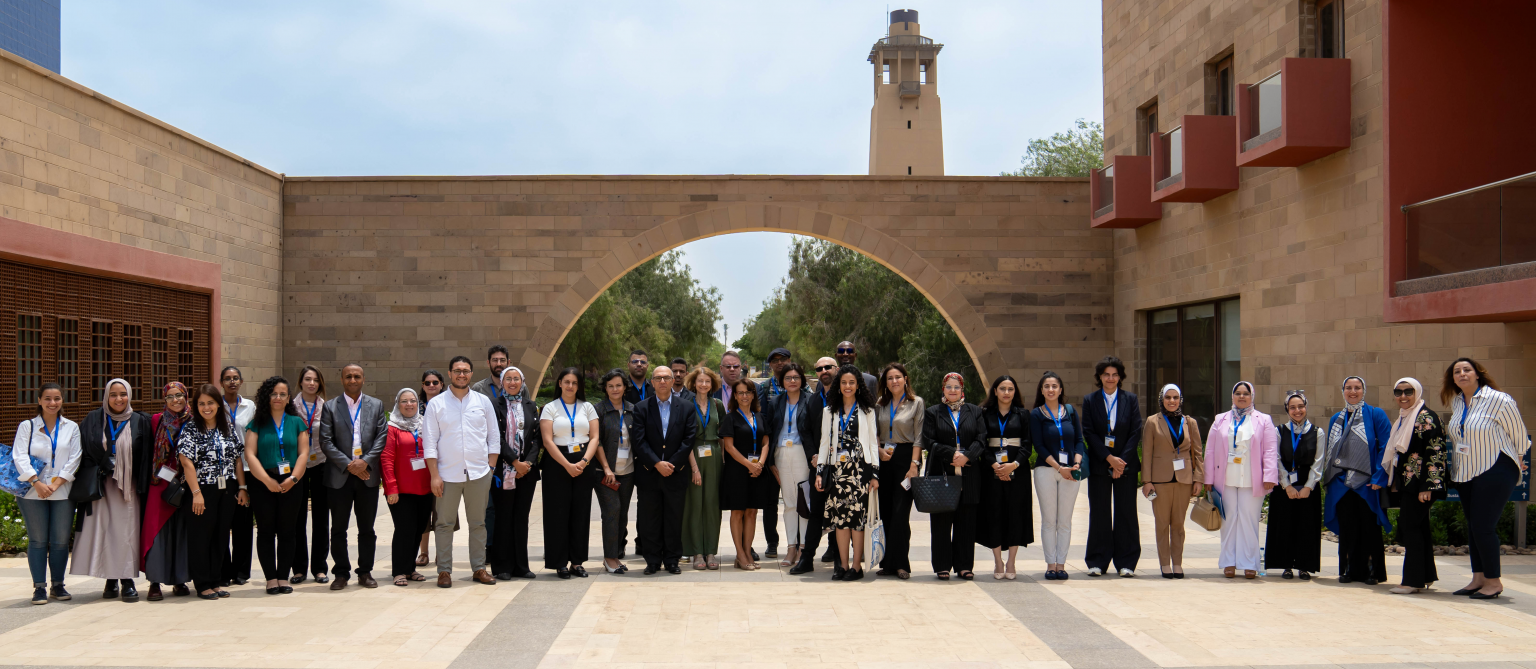
I then attended two very relevant events. On 30 April-1 May, I was at a Workshop on Driving Adoption of Worker-Centric Data Enrichment Guidelines and Principles, organised by Partnership on AI (PAI) and Fairwork in New York city to bring together representatives of AI companies, data vendors and platforms, and researchers. The goal was to discuss options to improve working conditions from the side of the employers and intermediaries. On 28 May, I was in Cairo, Egypt, to attend the very first conference of the Middle East and Africa chapter of INDL (International Network on Digital Labour), the research network I co-founded. It was a fantastic opportunity to start opening the network to countries that were less present before, and whose voices we would like to hear more.
August is a quieter month (but I greatly enjoyed a session at the Paralympics in Paris!), so I’ll jump to September. Lots of activities: a trip to Cambridge, UK, and a workshop on disinformation at the Minderoo Centre for Technology and Democracy; a workshop on Invisible Labour at Copenhagen Business School in Denmark; and a one-day conference on gender in the platform economy in Paris. Another publication came out: a journal article, in Spanish, on Argentinean platform data workers.
At the end of October, and until mid-November, I travelled to Chile for the seventh conference of the International Network on Digital Labour (INDL-7), which I co-organised. It was an immensely rewarding experience. I took the opportunity to strengthen my linkages and collaborations with colleagues there. It was a very intense, and super-exciting, time: after INDL-7 (28-30 October), I spent a week in Buenos Aires, Argentina, where I co-presented work in progress at the XV Jornadas de Estudios Sociales de la Economía, UNSAM. I then returned to Chile where I gave a keynote at the XI COES International Conference in Viña del Mar, Chile, on 8 November, and another at the ENEFA conference in Valdivia (Chile) on 14 November. I also gave a talk as part of the ChiSocNet series of seminars in Santiago, 11 November.
As part of a large, interdisciplinary European research project, we are seeking a motivated, open-minded student to join CNRS (specifically, the Centre for Research in Economics and Statistics, CREST) in Palaiseau, France, for three years.
The thesis aims to model the production and dissemination of ‘fake news’ in situations of uncertainty and socio-economic inequality. A rich sociological literature suggests that actors contextualise messages received and emitted as questions or answers, interpret them according to their recipients and senders, and assess their social acceptability within their own networks of relationships, taking into account their relative position. Building on this research, the goal is to identify the social processes underpinning misinformation-generating digital communications: collective identity, inequalities of status or authority, hierarchy of shared norms. This will enable interpreting the online social interactions through which actors collectively judge the (appropriate or inappropriate) quality of a message or information and then decide whether to relay or share it – and with whom. In particular, the thesis work will contribute to: 1/ drawing up a state of the art, mainly within sociology but open to the neighbouring disciplines which have also addressed these questions; 2/ illustrating and testing these theories through an empirical analysis of a digital database, mainly with quantitative methods, which may be enriched through a small complementary qualitative fieldwork; 3/ to contribute to the preparation of guidelines that help information professionals and policy-makers to detect the sources and modalities of emergence and propagation of misinformation.
The thesis will be done within the framework of the interdisciplinary project “AI-based-technologies for trustworthy solutions against disinformation” (AI4TRUST), funded by the European Union over the period 2023-2026, involving 17 partners (research institutions and media professionals) in 10 countries, and coordinated by Fondazione Bruno Kessler (Italy).
The AI4TRUST project aims to build a hybrid system, with advanced artificial intelligence solutions capable of cooperating with humans in the fight against disinformation. The new algorithms that will be developed in this framework, constantly checked and improved by human fact-checkers, will monitor multiple online social platforms in nearly real time, analysing text, audio, and visual contents in several languages. The resulting quantitative indicators, including infodemic risk, will be inspected under the lens of social and computational social sciences, to build the trustworthy elements required by media professionals.
The successful candidate will have the opportunity to join a group of highly motivated scientists and practitioners from across the continent; to participate in collaborations with other teams working on the project in an interdisciplinary framework; to attend regular meetings with the project’s principal Investigator, the scientists and experts involved, and public decision-makers; to present and publish research results in international conferences and journals.
The ideal candidate has a good background in quantitative sociology or in a STEM discipline (e.g., mathematics, statistics, computer science) with a strong interest in societal issues and challenges. A very good knowledge of English, an interdisciplinary approach and the ability to work in teams are essential.
Candidates should apply on the CNRS portal, where they will also find more details.
I am pleased to co-organize with Vincent Lorant of UCLouvain a special session on “The visualization of personal networks” at the forthcoming INSNA Sunbelt conference (12-16 July 2022, Cairns, Australia, and online).
Personal network data collection methods allow describing the composition and the structure of an individual’s (hereafter ego) social network. This method has been implemented in different domains such as migration, drug use, mental health, aging, education, and social welfare. Over the last years, these data have also been used to provide respondents with visualizations of their personal network, using different algorithms and customizing results through computer assisted data collection. Visualization gives valuable feedback to the respondent, improves data validity and may trigger positive behavioural changes, notably in vulnerable individuals or groups. Yet, visualization is not a free lunch. Recent research has evidenced the ethical dilemmas of providing such feedback to individuals: ego’s social life is being exposed, the researcher may be exposed as well, and such feedback may imply some contractual exchanges or therapeutic implications that require attention.
This session aims to describe the stakes of different visualization approaches to personal networks with different populations. We welcome qualitative and quantitative papers addressing issues related to the implementation of visualization or reports of personal networks in terms of techniques, levels of respondent’s satisfaction with visualization, conditions under which visualization is recommended or discouraged, and effects of the personal network visualization for the respondent.
More information on the conference and the submission process is available here.
There are differences of course: theirs is a large multi-country study while we focused on one national setting (France). Also: Kässi et al. consider online labour in general, while we looked specifically at micro-work.
Nevertheless, there are striking similarities. Both studies included larger as well as smaller and more peripheral platforms, often left aside in previous research. Both started from the numbers of registered users declared by the platforms in scope, although this is likely an upper bound. Indeed registering may not mean using, and for example researchers (like ourselves) and journalists would register only to observe, especially when registration is open and easy.
Also, both studies used web traffic analysis data but for different purposes. We used them as an estimate of minimally active users – those who connect at least monthly, as per the definition given by the providers of these data. For the platforms we observed, these numbers tend to be lower than registrations.
Instead, Kässi et al. have used these data to assess registration numbers for the platforms that do not report them. My first reaction would be to think their estimates are likely a lower bound. But presumably their use of a mix of sources, and the seriousness and caution with which they have conducted their estimate, provide enough correction.
Finally, both studies attempted to correct estimates downward by taking into account multi-homing – the tendency of users to rely on multiple platforms. The coefficient of Kässi et al. is 1.83, ours was 1.27. The gap is due to the fact that we focused only on micro-work: if we had counted participation across all types of online labour platforms, our coefficient would be just below 2 – not far from theirs! Kässi et al. also correct for the possibility of multiple workers using a single account, which we did not observe in our French sample. One might imagine other corrections depending on observed usages. For example my ongoing Latin American study of micro-workers suggests that there are unofficial sales and purchases of highly rated platform accounts, more likely to access better-paying tasks – again, something we did not observe in France. Kässi et al. rightly note that all these corrections come from ad hoc surveys and should be interpreted with caution.
Overall, I would say that both studies point to the need to put in place new and creative methods to account for these new forms of labour that traditional statistical studies fail to capture well. The price to pay, as both studies stress, is a high degree of uncertainty. I also dare suggest that both are mixed-method studies: while the design is essentially quantitative, input from smaller and even qualitative research is crucial – for example to get insight into multi-homing and multi-working.
Before concluding, let us recall the key results. Kässi et al. reckon that there are 163 million freelancer profiles registered on online labour platforms globally, of whom approximately 19 million have worked at least once, and 5 million work more intensely. We estimated that approximately 260,000 French residents are registered with micro-work platforms, of whom some 50,000 are ‘regular’ workers who do micro-tasks at least monthly, and a more restrictive measure of ‘very active’ workers would decrease this figure to 15,000.
Are these numbers large or small? Curiously, our French study attracted both criticisms: some worried that we might be overstating the importance of micro-work, others wondered why we bothered for such a tiny part of national GDP. It is not easy to answer this question, as the answer depends on the perspective taken and the goals – the same numbers would mean different things to policymakers and researchers, for example. Nevertheless, I think that the point that is important to all, is to say that this population exists and needs attention – despite its limited visibility and the fuzzy boundaries that make it so difficult to assess its size.
In the late 2000s, voices suggesting that our societies might be nearing the ‘end of privacy’ became increasingly deafening. Our cultural, political and regulatory environment was on the verge of major transformation – so went the narrative. Businesses rejoiced as notoriously, less privacy and more information oils the economy.
In a video interview with Italian media Idee Sottosopra, I review the courses of action taken by various stakeholders, in particular Internet companies, and examine their conflicts and controversies. I show how the very concept of privacy, inherited from a long legal and judicial tradition, should be revised and redefined to appropriately describe today’s online interactions.
Overall, there is no deterministic and inevitable tendency to exclude privacy from our societies, but rather a tension between social forces for and against privacy, which has accompanied the advent of the digital economy and especially social media. The positions of stakeholders, especially users, are often ambiguous, and social media companies attempted to leverage this ambiguity to their own advantage.
Yet civil society reactions have been stronger and stronger, and after initial David-vs-Goliath attempts of individuals and small associations, more and more authoritative institutions have taken seriously the defence of privacy. We are no longer left to costly and little-visible individual choices, and especially after entry into force of GDPR in Europe, we have now an unprecedented opportunity to act at a more systemic level.
Big Data. L’ipotesi della fine della della Privacy | Società Digitale | Idee Sottosopra
What is it about? ‘Micro-work’ consists of fragmented data tasks that myriad providers execute on online platforms. While crucial to the development of data-based technologies, this little visible and geographically spread activity is particularly difficult to measure. To fill this gap, we combined qualitative and quantitative methods (online surveys, in-depth interviews, capture-recapture techniques, and web traffic analytics) to count micro-workers in a single country, France. On the basis of this analysis, we estimate that approximately 260,000 people are registered with micro-work platforms. Of these some 50,000 are ‘regular’ workers who do micro-tasks at least monthly, and we speculate that using a more restrictive measure of ‘very active’ workers decreases this figure to 15,000. This analysis is important to better understand platform labour and the labour in the digital economy that lies behind artificial intelligence.
Table ronde, Sciences Po Paris, 6 décembre 2018, 18h00
Pour que la recherche en sciences sociales puisse pleinement tirer profit des grandes bases de données numériques, un verrou reste à lever : l’accès à ces données est limité, inégalement distribué, et entouré d’un flou juridique et déontologique. Nous proposons d’en discuter à l’occasion de la parution du numéro spécial de la Revue Française de Sociologie sur “Big data, sociétés et sciences sociales” (n. 59/3). Cette table ronde réunit les chercheur.e.s avec d’autres parties prenantes publiques et
privées.
Avec :
Garance Lefèvre, Policy senior associate, Uber
Roxane Silberman, Conseillère scientifique, Centre d’Accès Sécurisé aux Données (CASD)
Sophie Vulliet-Tavernier, Directrice des relations avec les publics et la recherche, Commission Nationale de l’Informatique et des Libertés (CNIL)
Les auteurs du numéro spécial.
Modérateurs : Gilles Bastin (Univ. Grenoble Alpes) et Paola Tubaro (CNRS), coordinateurs du numéro spécial.
Entrée libre et gratuite, dans la limite des places disponibles: pour s’inscrire, cliquez ici.
Accès : Sciences Po, salle Goguel. Entrée par le 27 rue Saint-Guillaume, 75007 Paris (traverser le jardin et prendre l’ascenseur jusqu’au dernier étage). La table ronde est organisée par la Revue Française de Sociologie en collaboration avec les Presses de Sciences Po. Elle sera suivie d’un pot.