Do you conduct research in social network analysis? Or in network science, with socio-economic data? If so, chances are that you encountered challenges when seeking ethical approval for your studies. Indeed, the nature of relational data and analyses raises unique issues, and ethical review boards are rarely attuned to dealing with these specificities.
I have had the opportunity to join forces with an international group of researchers help the community exit this impasse. We have pulled together existing knowledge, experience, and solutions from across the world, aiming to share them with interested researchers. By so doing, we want to make ethics-related processes less clumsy to navigate and implement. The idea is to consolidate existing best practices and to facilitate their usage, not to impose new restrictions or requirements. The result is meant to be a resource that researchers can draw on to demonstrate and justify the ethically appropriate aspects of their research to their review boards.
The idea is also to go beyond the dividing line between social network analysis in the social science tradition, and network scientists in the physics/complexity/computer science traditions. Indeed, our team includes representatives of both areas. Now, our piece has come out – and it is freely accessible, in (gold) open access. We are excited to share the results of these efforts, and we hope they will facilitate further advances in network research. In addition to the published article, there is also a supporting website, with a synthesis of our main recommendations – a practical tool for anyone who has to negotiate with an ethical review board.
Ortiz Ruiz F, Tubaro P, Molina JL, et al. Recommendations for conducting ethical network research. Network Science. 2026;14:e17, doi:10.1017/nws.2026.10034
There are two main ways in which a discipline like sociology engages with artificial intelligence (AI) and is affected by it. In a previous post, I discussed how the sociology of AI understands technology as embedded in socio-economic systems and takes it as an object for research. Here, focus is on sociology with AI, indicating that the discipline is integrating AI into its methodological toolbox.
AI technologies were designed for other-than-research purposes, but they may be repurposed. The editors of a special issue of Sociologica last year stress that, ten years ago, digital methods presented similar challenges: for example, using tweets to make claims about the social world required us to understand how people used Twitter in the first place. We also needed to understand which people used Twitter at all, and what spaces of action the architecture and Terms of Use of this platform allowed. Likewise, using AI technologies can serve sociologists insofar as efforts are made to understand the technological (and socio-economic) conditions that produced them. Because AI systems are typically blackboxed, this requires, to begin with, developing exploration techniques to navigate them. For example, the plot below is from a recent paper that asked five different LLMs to generate religious sermons and compared the results (readability scores) by religious traditions and race. It finds that Jewish and Muslim synthetic sermons were constructed with significantly more difficult reading levels than were those for evangelical Protestants, and that Asian religious leaders were assigned more difficult texts than other groups. It is a way to uncover how models treat religious and racial groups differently, although it remains difficult to detect precisely which factors affect this result.
Robust regression coefficients predicting readability scores by religion, race, and model. Source: Tom J.C., Ferguson T.W. & Martinez B.C. 2025. Religion and racial bias in Artificial Intelligence Large Language Models. Socius: Sociological Research for a Dynamic World, 11. https://doi.org/10.1177/23780231251377210
That said, how can AI help us methodologically? To answer this question, it is useful to look at qualitative and quantitative approaches separately. Qualitative research, traditionally viewed and practiced as an intensely human-centred method, may seem at first sight incompatible with it. However, use of computer-assisted qualitative data analysis (with tools such as Nvivo) is now common among qualitative researchers, though it faced some degree of scepticism at the beginning. Attempts to leverage AI move forward this agenda, and the most common application so far is automated transcription of interviews through speech recognition technologies. AI-powered tools make this otherwise tedious task more efficient and scalable. A recent special issue of the International Journal of Qualitative Methods maps a variety of other usages, less common and more experimental: for example, considering that even the best models for audio transcription are not as accurate as humans, LLMs appear as tools to facilitate and speed up transcription cleaning. There are also some attempts at using LLMs as instruments for coding and thematic analysis: for example, some authors have examined inter-coder reliability between ‘human only’ and ‘human-AI’ approaches. Others have used AI image generation like vignettes – as a tool for supporting interview participants in articulating their experiences. Overall, the use of AI remains experimental and marginal in the qualitative research community. Those who have undertaken these experiments find the results encouraging, but not perfect.
In quantitative research, some AI tools are already (relatively) widely used: in particular, natural language processing (NLP) to process textual data like corpora from the press or media. More recent applications leverage generative AI, especially large language models (LLM). Outside practices like literature review and code generation/debugging, which are common to multiple disciplines, three applications are specifically sociological and worth mentioning. First, in experimental research, there are some attempts to examine how the introduction of AI agents in interaction games shapes the behaviour of the humans they play with. As discussed by C. Bail in an insightful PNAS article, the extent to which generative AI is capable of impersonating humans is nevertheless subject to debate, and it will probably evolve over time. Second, L. Rossi and co-authors outline that in agent-based models (ABM), an idea is to use LLMs to create agents that are more capable of capturing a larger spectrum of human behaviours. While this approach may provide more realistic descriptions of agents, it re-ignites a long-standing debate in the field: indeed, many believe that increasing the complexity of agents is undesirable when emergent collective dynamics can emerge from more parsimonious models. It is also unclear how the performance of LLMs within ABMs should be evaluated. Shall we say that they are good if they reproduce known collective dynamics within ABMS? Or, should they be assessed based upon their capacity to predict real-world outcomes? Third, in survey research, the question has arisen whether LLMs can simulate human populations for opinion research. Some studies have tested this possibility, with mixed results. The most recent available evidence, in an article by J. Boelaert and co-authors, is that: 1) current LLMs fail to accurately predict human responses, 2) they do so in ways that are unpredictable, as they do not systematically favor specific social groups, and 3) their answers exhibit a substantially lower variance between subpopulations than what is found in real-world human data. In passing, this is evidence that so-called ‘bias’ does not necessarily operate as expected – LLM errors do not stem primarily from unbalanced training data.
These applications face specific ethical challenges. First, studies that require humans to interact with AI may expose them to offensive or inaccurate information, the so-called ‘AI hallucinations’. Second, there are new concerns about privacy and confidentiality. Most GenAI models are the private property of companies: if we use them to code in-depth interviews about a sensitive topic, the full content of these interviews may be shared with these companies, often not bound by the same standards and regulations in terms of personal data protection. Third, the environmental impact of these models is high, in terms of energy to run the system, water to cool servers in data centres, metal extraction to build devices, and production of e-waste. The literature on AI-as-object also warns that there is a cost in terms of the unprotected human work of annotators.
Another limitation is that is that research with Generative AI is difficult to replicate. These models are probabilistic in nature: even identical prompts may produce different outputs, in ways that are not well understood as of today. Also, models are constantly being fine-tuned by their producers in ways that we as users do not control. Finally, different LLMs have been found to produce substantially different results in some cases. Many of these issues are due to the proprietary nature of most models – so much so that some authors like C. Bail believe that open-source models devoted to, and controlled by, researchers can help address some of these challenges.
Overall, AI has slowly entered the toolbox of the sociologist, and except for some applications that are now commonplace (from automated transcriptions to NLP), its use has not completely revolutionised practices. This pattern is not exclusive to sociology. My own study of the diffusion of AI in science until 2021, as part of the ScientIA project led by F. Gargiulo, showed limited penetration in almost all disciplines, although the last two years have seen a major acceleration. The opportunities that AI offers are promising, although a lot are more hypothetical than real at the moment. We still see calls that invite sociologists and social scientists to embrace AI, but the number of realizations is still small. Almost all applications devote time to consider the epistemological, methodological, and substantive implications. A question that often emerges concerns the nature of bias. The AI-as-object perspective challenges the language of bias, and we see the same here, though from a different perspective. There’s still no shared definition of bias (or any substitute for this term). More generally, patterns are similar in qualitative and quantitative studies. The guest-editors of last year’s special issue of Sociologicasuggest that, like digital methods 10-15 years ago, generative AI is supporting a move beyond the traditional qualitative/quantitative divide.
Concluding, both Sociology-of-AI and Sociology-with-AI exist and are important, but they are not well integrated. This is one of the bottlenecks for the development of the methodological toolbox of sociology, but also for the development of an AI that is useful and positive for people and societies. In part, this may be due to lack of adequate (technical) training for part of the profession, or to the absence of guidelines (for ethics and/or scientific integrity). But perhaps, the real obstacles are less immediately visible. One of them is the difficulty to judge the uptake of AI in our discipline: are we just feeding the hype if we use it? Or are we missing a major opportunity to make sociology more relevant/stronger if we don’t? The other concerns the questions and issues that go beyond the specificities of sociology. How to continue interacting with other disciplines, while upholding the distinctive contribution of sociology?
We examine the implications of the use of digital micro-working platforms for scientific research. Although these platforms offer ways to make a living or to earn extra income, micro-workers lack fundamental labour rights and ‘decent’ working conditions, especially in the Global South. We argue that scientific research currently fails to treat micro-workers in the same way as in-person human participants, producing de facto a double morality: one applied to people with rights acknowledged by states and international bodies (e.g. Helsinki Declaration), the other to ‘guest workers of digital autocracies’ who have almost no rights at all.
Research on social networks raises formidable ethical issues that often fall outside existing regulations and guidelines. State-of-the-art tools to collect, handle, and store personal data expose both researchers and participants to new risks. Political, military and corporate interests interfere with scientific priorities and practices, while legal and social ramifications of studies of personal ties and human networks come to the surface.
The proposed special section aims to critically engage with ethics in research related to social networks, specifically addressing the challenges that recent technological, scientific, legal and political transformations trigger.
Following a successful workshop on this topic that was held in December 2017 in Paris, we welcome submissions that critically engage with ethics in research related to social networks, possibly based on reflective accounts of first-hand experiences or case studies, taken as concrete illustrations of the general principles at stake, the attitudes and behaviors of stakeholders, or the legal and institutional constraints. We are particularly interested in novel, original answers to some unprecedented ethical challenges, or the need to reinterpret norms in ambiguous situations.
Fueled by increasingly powerful computing and visualization tools, research on social networks is flourishing. However, it raises ethical issues that largely escape existing codes of conduct and regulatory frameworks. The economic power of large data platforms, the active participation of network members, the spectrum of mass surveillance, the effects of networking on health, the place of artificial intelligence: so many questions in search of solutions.
Social networks, what are we talking about?
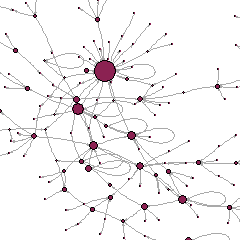
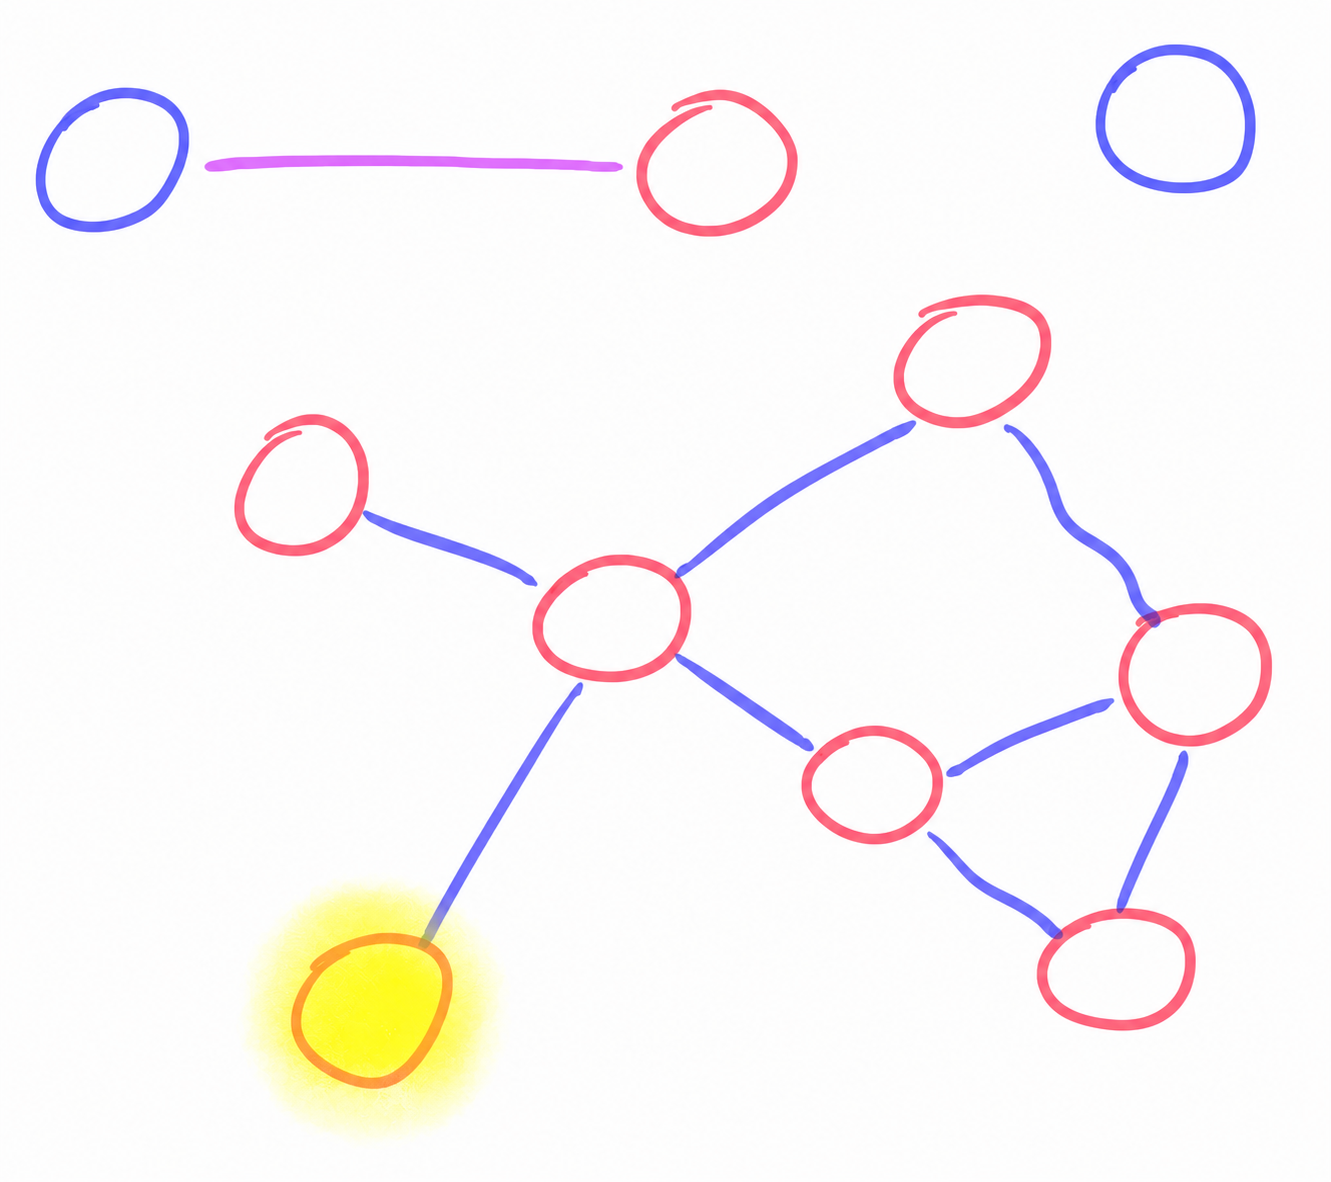
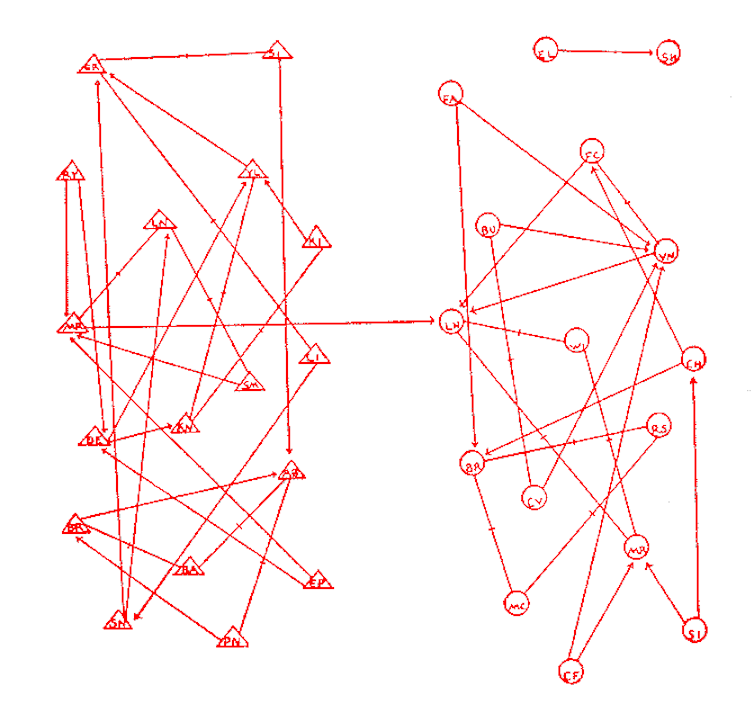
The expression “social network” has become common, but those who use it to refer to social media as Facebook or Instagram often ignore its origin and its true meaning. The study of social networks precedes the advent of digital technologies. Since the 1930s, sociologists have been conducting surveys to describe the structures of relationships that unite individuals and groups: their “networks”. These include, for example, advice relationships between employees of a company, or friendship ties between students in a school. These networks can be represented as points (students) united by lines (links).
Figure 1 : a social network of friendship ties between students in a school. Circles = girls, triangles = boys, arrows = ties. J.L. Moreno, Who shall survive? 1934.
Before any questioning on the social aspects of Facebook and Twitter, this research shed light on, for example, marital role segregation, importance of “weak ties” in job search, informal organization of firms, diffusion of innovations, formation of business elites, social support for the sick or elderly. Designers of digital platforms such as Facebook have picked up some of the analytical principles on which these works were based, developing them with the mathematical theory of graphs (though often with less attention to the social issues involved).
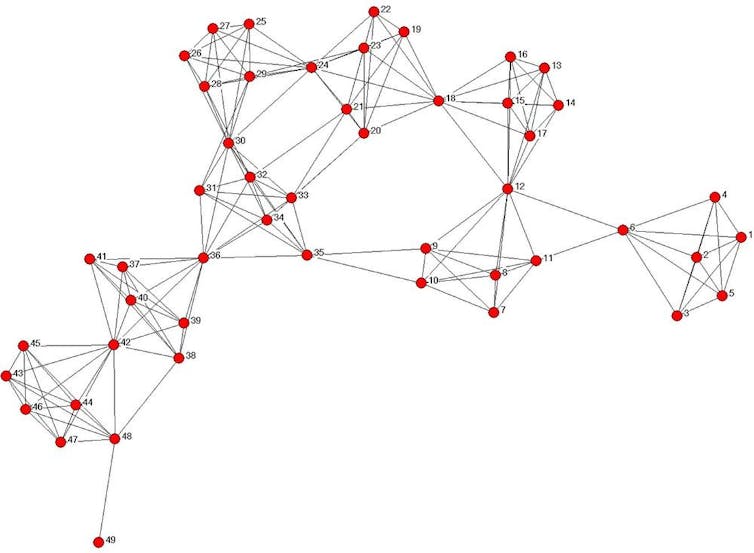
Early on, researchers in this field realized that the traditional principles of research ethics (focusing on informed consent of study participants and anonymization of data) were difficult to ensure. By definition, social networks research is never about a single individual, but about relationships between this individual and others – their friends, relatives, collaborators or professional advisors. If the latter are reported by the respondent but are not themselves included in the study, it is difficult to see how their consent could be obtained. What’s more, results can be difficult to anonymize, in that visuals are sometimes disclosive even in the absence of personal identifiers.
Ethics in the digital society: a minefield
Academics have long been thinking about these ethical difficulties, to which a special issue of the prestigious Social Networks journal was dedicated as far back as 2005. Today, researchers’ dilemmas are exacerbated by the increased availability of relational data collected and exploited by digital giants like Facebook or Google. New problems arise as the boundaries between “public” and “private” spheres become confused. To what extent do we need consent to access messages that digital service users send to their contacts, their “retweets”, or their “likes” on their friends’ walls?
These sources of information are often the property of commercial enterprises, and the algorithms they use likely bias observations. For example, can we interpret in the same way a contact created spontaneously by a user, and a contact created as a result of an automated recommendation system? In short, the data do not speak for themselves, and before thinking about their analysis, we must question the conditions of their use and the methods of their production. They largely depend on the software architectures imposed by platforms as well as their economic and technical choices. There is a real power asymmetry between platforms – often the property of large multinational companies – and researchers – especially those working in the public sector, and whose objectives are misaligned with investors’ priorities. Negotiations (if possible at all) are often difficult, resulting in restrictions to proprietary data access – particularly penalizing for public research.
Other problems arise as a researcher may even use paid crowdsourcing to produce data, using platforms like Amazon Mechanical Turk to ask large numbers of users to complete a questionnaire, or even to download their online contact lists. But these services raise numerous questions in terms of workers’ rights, working conditions and appropriation of the product of work. The resulting uncertainty hinders research that could otherwise have a positive impact on knowledge and on society at large.
Availability of online communication and publication tools, which many researchers are now seizing, increases the likelihood that research results may be diverted for political or business purposes. If the interest of military and police circles for the analysis of social networks is well known (Osama Bin Laden was allegedly located and neutralised following the application of social network analysis principles), these appropriations are more frequent today, and less easily controllable by researchers. A significant risk is the use of these principles to suppress civic and democratic movements.
Restrictions and prohibitions would likely aggravate the constraints that already weigh on researchers, without helping them overcome these obstacles. Rather, it is important to create conditions for trust and enable researchers to explore the full extent and importance of online and offline social networks – allowing them to capture salient economic and social phenomena while remaining respectful of people’s rights. Researchers should take an active role, participating in the co-construction of an adequate ethical framework, grounded in their experience and self-reflective attitude. A bottom-up process involving academics as well as citizens, civil society associations, and representatives of public and private research organizations could then feed these ideas and thoughts back to regulators (such as ethics committees).
Research on social networks is experiencing unprecedented growth, fuelled by the consolidation of network science and the increasing availability of data from digital networking platforms. However, it raises formidable ethical issues that often fall outside existing regulations and guidelines. New tools to collect, treat, store personal data expose both researchers and participants to specific risks. Political use and business capture of scientific results transcend standard research concerns. Legal and social ramifications of studies on personal ties and human networks surface.
We invite contributions from researchers in the social sciences, economics, management, statistics, computer science, law and philosophy, as well as other stakeholders to advance the ethical reflection in the face of new research challenges.
The workshop will take place on 5 December 2017 (full day) at MSH Paris-Saclay, with open keynote sessions to be held on 6 December 2017 (morning) at Hôtel de Lauzun, a 17th century palace in the heart of historic Île de la Cité.
Let us know if you wish to be panel discussant or session chair by 20 October 2017 (send to: recsna17@msh-paris-saclay.fr).
Acceptance notifications will be sent by 31 October 2017.
Registration is free but mandatory: speakers (and discussants and chairs) should register between 15 October and 15 November 2017, other attendees by 30 November 2017.
Keynote Speakers
José Luis Molina, Autonomous University of Barcelona, “HyperEthics: A Critical Account” Bernie Hogan, Oxford Internet Institute, “Privatising the personal network: Ethical challenges for social network site research”
Scientific Committee
Antonio A. Casilli (Telecom ParisTech, FR), Alessio D’Angelo (Middlesex University, UK), Guillaume Favre (University of Toulouse Jean-Jaurès, FR), Bernie Hogan (Oxford Internet Institute, UK), Elise Penalva-Icher (University of Paris Dauphine, FR), Louise Ryan (University of Sheffield, UK), Paola Tubaro (CNRS, FR).
Some time ago, I wrote a post on ethical issues in research with secondary data – a somewhat grey area, where students and scholars often feel guidance is insufficient. Even more complex is research with internet data – neither primary nor secondary strictly speaking, but “big” data. A recent case fuelled an international debate on how researchers should deal with data that are, apparently, accessible to all on the web: a Danish graduate student published a large dataset of users of the online dating site OkCupid (he apparently did so without any institutional backing, and Aarhus University where he studies, is now on the case). Michael Zimmer, a specialist of information studies and the policy and ethics of online research, properly summarizes the issues in a recent Wired article:
Don’t say that “the data are already public”. The fact that OkCupid users knowingly share some personal information, does not mean they consent to it being used for purposes other than interactions with other users on that site. By scrapping data, one may be able to put together the whole history of users’ presence on that platform, revealing more of their life or personality than they themselves are aware of. More dangerously, data extracted in this way might in some cases be matched with other information, thereby potentially becoming much more disclosive than what the persons concerned ever intended or agreed. And the disclosure may be aggravated by releasing the data outside the platform.
It is often believed that use of secondary data relieves the researcher from the burden of applying for ethical approval – and sometimes, from thinking about ethics altogether. But the whole process of research involves ethical considerations, whether or not any primary data collection is involved. This starts from the initial design of the study, which should aim at the public good (and at the very least should do no harm) and continues until communication of results, which should ensure transparency, publicness and replicability. More specifically, what ethical issues will the data collection and analysis stages involve, when secondary data are used?
Secondary data are usually defined as those that were collected as part of a different research, with purposes other than those of the present study. They may be official statistical data (census for example, but also, increasingly, administrative data), data gathered by commercial operators (time series of stock prices for example), and researchers’ data from past projects. They are more often quantitative, although secondary analysis of qualitative data is becoming more and more common.
Weighing risks and benefits
Use of secondary data is in itself, a highly ethical practice: it maximizes the value of any (public) investment in data collection, it reduces the burden on respondents, it ensures replicability of study findings and therefore, greater transparency of research procedures and integrity of research work. But the value of secondary data is only fully realized if these benefits outweigh the risks, notably in terms of re-identification of individuals and disclosure of sensitive information.
For this to happen, use of secondary data must meet some key ethical conditions:
Data must be de-identified before release to the researcher
Consent of study subjects can be reasonably presumed
Outcomes of the analysis must not allow re-identifying participants
Use of the data must not result in any damage or distress


 Data Big and Small
