The “Impact of Social Science” blog of the London School of Economics has, in the past few weeks, published a series on “Philosophy of data science“. Each installment is an interview conducted by sociologist Mark Carrigan with a key contributor to the social science reflection on data.
Tag Archives: Social science research
The power of survey data: Eurostat Users’ Conference
In the age of big data, social surveys haven’t lost their appeal and interest. Surveys are the instrument through which governments, for a long time, have gathered information on their population and economy to inform their choices. Interestingly, surveys conducted by, or for, governments are the best in terms of quality and coverage: because significant resources are invested in their design and realization, and especially because participation can be made compulsory by law (they are “official”), their sampling strategies are excellent and their response rates are extremely high. (Indeed, official government surveys are practically the only case in which the “random sampling” principles taught in theoretical statistics courses are actually applied). In short, these are the best “small data” available — and their qualities make them superior to many a (usually messy) big data collection. It is for this reason that surveys from official statistics have always been in high demand by social researchers.
Continue reading “The power of survey data: Eurostat Users’ Conference”
Data and social networks: empowerment and new uncertainties (in Italian)
I gave a presentation on the topic of “Data and social networks: empowerment and new uncertainties” at the Better Decisions Forum on Big Data and Open Data that took place in Rome on 12 November 2014. The event brought together six speakers from different backgrounds on a variety of topics related to data, and participants were businesspeople, public administration managers, journalists, data and computer scientists.
Here is a video of my talk:
Unfortunately as you will have noticed, the slides are not always very clearly visible, so it’s better to download them from their original source:
My interview before my talk:
See? I am trying to stick to my 1st-January commitment of blogging more this year…
“Pro” ana? Sociability and support in eating disorder online communities
This article was first published on Discover Society, November 2014.
Last June, a group of Italian MPs proposed jail terms and fines for authors of so-called “pro-ana” (anorexia) and “pro-mia” (bulimia) websites. These are self-styled online communities on eating disorders which are viewed as promoting extreme dieting and unhealthy eating practices. France and the United Kingdom preceded Italy’s attempt to pass restrictive legislation as far back as 2008-9, and many internet service providers also endeavoured to ban these contents.
But the potential spread of health-hazardous behaviours is probably only one side of the coin, and these websites might also channel health-enhancing assistance, advice, and support (Yeshua-Katz & Martins 2013). In fact a closer look reveals that website users carefully manage their online socialisation to address their health challenges. Online social spaces enable discussion around the illness and constitute a complement, albeit an admittedly imperfect one, to formal healthcare services. There is no rejection of standard health norms in the name of some extreme ideal of thinness but rather a need – or perhaps, a cry – for extra support.
A social science approach brings out these results. The effect of web interactions on health does not only depend on website contents, but also on how people actually use them, share them, and access resources through them. The social, rather than just clinical dimension of eating disorders, recognized long before the advent of the web (Bell 1985, Orbach 1978), becomes ever more relevant in the current context and calls for a more comprehensive view of the “ana” and “mia” social universe.
Continue reading ““Pro” ana? Sociability and support in eating disorder online communities”
Sociology in 2014: rediscovering methods
I was back last week from the annual conference of British Sociological Association (BSA) in Leeds, and as usual, I try to put down my impressions as long as they’re still fresh in my mind. I wasn’t very quick, though, and the BSA’s members newsletter has already come out with comments and short reports about the plenaries, the prizes awarded, and the conference overall. While the conference is described as having been “very vibrant and sociable”, with “exciting conversations” during the breaks and a “diverse mixture of topics” that “reflected the breadth of interests”. My own feelings, I confess, are a bit more mixed.

In 2012, the BSA conference was followed by a lively debate after an article, by Aditya Chakrabortty on the Guardian, where he complained about the discipline’s lack of engagement with the financial crisis. He pointed to the BSA press releases featuring research on “older bodybuilders”, and to time devoted to the “holistic massage industry” at the conference, as evidence of what he saw as a retreat from public space. The BSA took the criticism very seriously and, apart from responding to the Guardian, put in place a massive effort to encourage public engagement. The 2013 conference was entitled “Engaging Sociology” and many sessions were dedicated to showing that the profession means it. Confrontation and comparison with economics was open and clear. A major project on social class was presented with all honours. The Sociology journal released a call for papers for a special issue to “Sociology and the Global Economic Crisis”.
This year, the “Changing Society” title aimed to stress continuity with last year’s efforts; yet it seems to me that we are back to business as usual. I had the impression that many paper presentations were on topics similar to the body builders and massage that Chakrabortty talked about. That’s why, as I said, my feelings are mixed.
Qualitative networks
Social Network Analysis (SNA) is booming, and many think it’s because of internet networks and big data. Yet social networks themselves are not new: people have always formed ties to one another, and online platforms such as Facebook, Twitter and LinkedIn only offer channels for networked interactions to occur. Counts and fancy visualisations of myriad likes and shares do not tell the whole story either: networks are primarily about exploring how ties connect us as individuals and as organisations or groups, and how our social relationships affect our lives and behaviours.
In this sense, smaller studies can still have much to teach us. These include not only quantitative, but also qualitative approaches. “Social” networks involve a world of meanings, feelings, relationships, attractions, dependencies, which have traditionally been at the heart of qualitative research and are amenable to a mixed-methods approach.
In this perspective, with the Social Network Analysis Group of the British Sociological Association (BSA-SNAG), I am organising a one-day small conference on “Mixed Methods Approaches to Social Network Analysis”, exploring how the combination of SNA and qualitative methods can enrich and deepen our understanding of network content in conjunction with network structure. The event will take place on 12 May 2014 at Middlesex University, London, and the programme is available here; to register online (deadline 30 April!) click here.
Small data and big models: Sunbelt 2014
Uh, it’s been a while… I should have written more regularly! All the more so as many things have happened this month, not least the publication of our book on the End-of-Privacy hypothesis. Well, I promise, I’ll catch up!
Meanwhile, a short update from St Pete Beach, FL, where the XXXIV Sunbelt conference is just about to end. This is the annual conference of the International Network for Social Network Analysis and in the last few years, I noticed some sort of tension between the (let’s call it like that — no offense!) old-school of people using data from classical sources such as surveys and fieldwork, and big data people, usually from computer science departments and very disconnected from the core of top social network analysts, mostly from the social sciences. This year, though, this tension was much less apparent, or at least I did not find it so overwhelming. There weren’t many sessions on big data this time, but a lot of progress with the old school — which in fact is renewing its range of methods and tools very fast. No more tiny descriptives of small datasets as was the case in the early days of social network analysis, but ever more powerful statistical tools allowing statistical inference (very difficult with network data — I’ll go back to that in some future post), hypothesis testing, very advanced forms of regression and survival analysis. In this sense, a highly interesting conference indeed. We can now do theory-building and modeling of networks at a level never experienced before, and we don’t even need big data to do so.
The keynote speech by Jeff Johnson, interestingly, was focused on the contrast between big and small data. Johnson has strong ethnographic experience with small data, including in very exotic settings such as scientific research labs at the South Pole and fisheries in Alaska. He combined social network analysis techniques, sometimes using highly sophisticated mathematical tools, with fieldwork observation to gain insight into, among other things, the emergence of informal roles in communities. His key question here was, can we bring ethnographic knowing to big data? And how can we do so?
My own presentation (apart from a one-day workshop I offered on the first day, where I taught the basis of social network analysis) took place this afternoon. I realize, and I am pleased to report, that it was in line with the small-data-but-sophisticated-modeling mood of the conference. It is a work derived from our research project Anamia, using data from an online survey of persons with eating disorders to understand how the body image disturbances that affect them are related to the structure of their social networks. The data were small, because they were collected as part of a questionnaire; but the survey technique used was advanced, and the modeling strategy is quite complex. For those who are interested in the results, our slides are here:
Network data, new and old: from informal ties to formal networks
Network data are among those that are changing fastest these days. When I say I study social networks, people almost automatically think of Facebook or Twitter –without necessarily realizing that networks have been around for, well, the whole history of humanity, long before the internet. Networks are just systems of social relationships, and as such, they can exist in any social context — the family, school, workplace, village, church, leisure club, and so forth. Social scientists started mapping and analysing networks as early as the 1930s. But people didn’t think of their social relationships as “networks” and didn’t always see themselves as “networkers” even if they did invest a lot in their relationships, were aware of them, and cared about them. The term, and the systemic configuration, were just not familiar. There was something inherently informal and implicit about social ties.
What has changed with Facebook and its homologues, is that the network metaphor has become explicit. People are now
accustomed to talking about “networks”, and think in systemic terms, seeing their own relationships as part of a more global structure. Network ties have become formal — you have to make a clear choice and action when you add a “friend” on Facebook, or “follow” someone on Twitter; you will have a list of your friends/followers/followees (whatever the specific terminology is) and monitor changes in this list. You know who the friends of your friends are, and can keep track of how many people viewed your profile /included you in their “lists” / mentioned you in their Tweets. Now, everyone knows what networks are –so if you are a social network researcher and conduct a survey like in the old days, you won’t fear your respondents may misunderstand. In fact, you may not even need to do a survey at all –the formal nature of online ties, digitally recorded and stored, makes it possible to retrieve your network information automatically. You can just mine network tie data from Facebook, Twitter, or whatever service your target populations happen to be using.
Continue reading “Network data, new and old: from informal ties to formal networks”
Training in European data: EU-SILC
Official statistical surveys are still the best sources of data in terms of quality. Practically, they are the only ones that apply random sampling and the legal obligation to respond makes the actual sample very close to the targeted one. No other approach to data collection can hope to do as well.
The European Union Statistics on Income and Living Conditions (EU-SILC) is an instrument aiming at collecting timely and
comparable cross-sectional and longitudinal multidimensional microdata on income, poverty, social exclusion and living conditions. It started in 2003 with a small group of participant countries, and was enlarged in 2004. It is one of the richest sources of information on the daily life conditions of Europeans.
EU-SILC data are available for research use, but many barriers exist and these data are actually underutilized. On the one hand, the fact that access is legally authorised does not make it practically straightforward – the application process can be lengthy and costly. On the other hand, the very handling of data requires some specific knowledge and skills.
The Data without Boundaries European initiative, aimed at moving forward research access to official data, organises a training programme on EU‐SILC with a specific focus on the longitudinal component. Local organization lies with Réseau Quetelet, host of the training course is GENES ‐ Groupe des Écoles Nationales d’Économie et Statistique both in Paris (France).
#bigdataBL
On Friday last week, the British Sociological Association (BSA) held an event on “The Challenge of Big Data” at the British Library. It was interesting, stimulating and relevant – I was particularly impressed by the involvement of participants and the very intense live-tweeting, never so lively at a BSA event! And people were particularly friendly and talkative both on their keyboards and at the coffee tables… so in honour of all this, I am choosing the hashtag of the day #bigdataBL as title here.
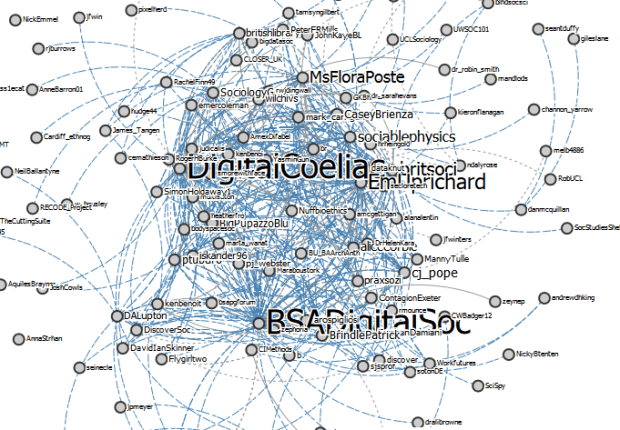
(Visualisation: http://www.digitalcoeliac.com/)
Some highlights:
- The designation of “big data” is from industry, not (social) science, said a speaker at the very beginning. And it is known to be fuzzy. Yet it becomes a relevant object of scientific inquiry in that it is bound to affect society, democracy, the economy and, well, social science.
- Big-data practices change people’s perception of data production and use. Ordinary people are now increasingly aware that a growing range of their actions and activities are being digitally recorded and stored. Data are now a recognized social object.
- Big data needs to be understood in the context of new forms of value production.
- So, social scientists need to take note (and this was the intended motivation of the whole event). The complication is that Big Data matter for social science in two different ways. First, they are an object of study in themselves – what are their implications for, say, inequalities, democratic participation, the distribution of wealth. Second, they offer new methods to be exploited to gain insight into a wide range of (traditional and new) social phenomena, such as consumer behaviours (think of Tesco supermarket sales data).
- Put differently, if you want to understand the world as it is now, you need to understand how information is created, used and stored – that’s what the Big Data business is all about, both for social scientists and for industry actors.